Explaining Basic DeepSeek in C/C++
Materials available at: http://forejune.co/cuda/
Recap
DeepSeek-Style MoE Decoder-Only Transformer
- MoE dynamically selects a subset of experts
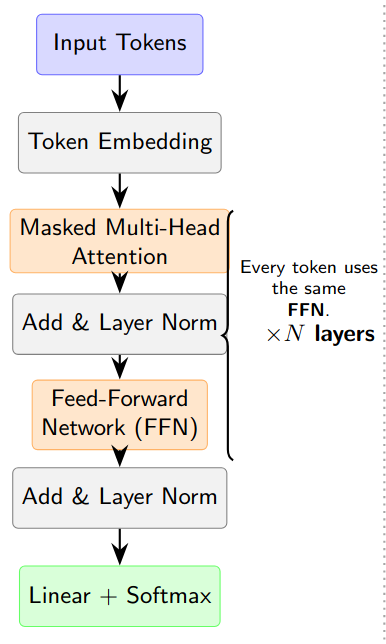
|
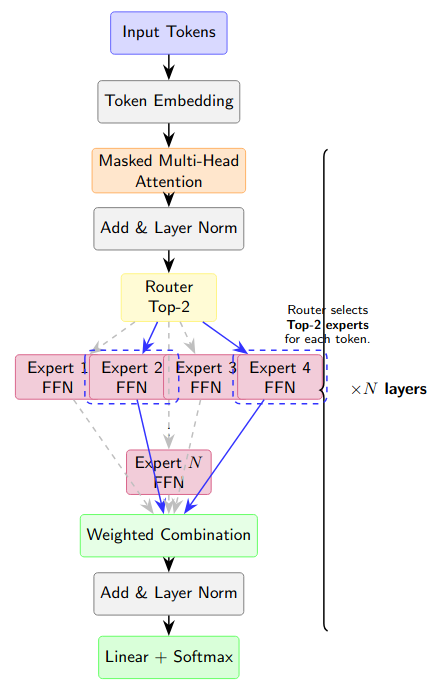
|
| Traditional Transformer       | DeepSeek MoE                                          |
| ----------------------------- | ----------------------------------------------------- |
| One FFN                       | Many FFNs ("experts")                                 |
| Every token uses the same FFN | Router chooses experts for each token                 |
| FFN is dense                  | FFN is sparse                                         |
| All FFN parameters are used   | Only a small subset of expert parameters is activated |
| No router                     | Router determines expert selection                    |
- FFN
We could organize the embeddings into an n x dmodel matrix n = number of tokens Suppose X is the embedding matrix : n x dmodel Weight matrix W1 expands the dimension to dff σ is a non-linear activation function (e.g. ReLU( z ) = max(0, z) ) Weight matrix W2 projects back to the model the dimension dmodelIn C/C++ psuedo code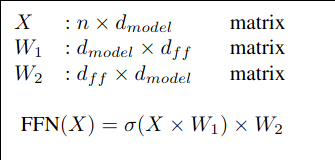 n x dmodel X
dmodel x dff W1
--------------------------------------
n x dff
dff x dmodel W2
--------------------------------------
n x dmodel FFN(X)
So the output has the same dimension as input X
using matrixd = vector<vector<double>>; // 2D vector of double matrixd X = ( // each token is a row token1, // X[1], in actual implementation this is X[0] token2, token3, ... tokenN ); // FFN matrixd Z = matmul(X, W1); // pre-activation matrixd F1 = relu( Z ); // F1 = f( X W1 ) matrixd F2 = matmul(F1, W2); // F2 = F1 W2 return F2; // n x d_model - MoE Formulation:
For a basic top-1 MoE, we could have N expert FFNs:
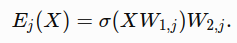
j = 1, 2, ..., N i = 1, ... ,n : token index j = 1, ... ,N : expert index
The router operates on each token row: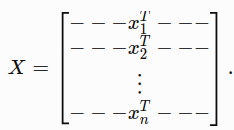 xiT = X[i] is a row of embedding matrix X, a 1 x dmodel row vector
xi is the corresponding dmodel x 1 column vector
-
Si = WR xi
		WR : N x dmodel
		xi :	 dmodel x 1
		Si : N x 	 1
Or in matrix form:
S[i][j] is the router score for token i and expert j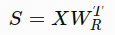 S : n x N
For each token i, we choose the maximum router score:
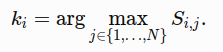
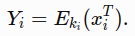
xiT : 1 x dmodel Yi : 1 x dmodel 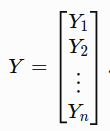
Output = LayerNorm(X + Y)
C/C++ Implementation
class MoE
{
protected:
    int N;		// number of experts
    int dModel;
    int d_ff;
    matrixd WR;		// N x dModel

    vector<FeedForward> Experts;  // FFN

    //cache
    vector<int>experts;		// indices to experts
public:
    // Constructor
    MoE(int N, int dModel, int d_ff );
    matrixd Scores(const matrixd& X);
    vector<int> routes(const matrixd& X);       // return n k_i

    matrixd forward(const matrixd& X);
    matrixd backProp(const matrixd &X, const matrixd &dL_dY,  double eta);
    void saveWeights(FILE *fp);
    void readWeights(FILE *fp);
};
|
// Constructor
// WR: N x dModel
MoE::MoE(int N, int dModel, int d_ff ) : N(N),
dModel(dModel), d_ff(d_ff)
{
initMatrix(WR, N, dModel);
for(int i = 0; i < N; i++){ // create N experts
FeedForward FFN(dModel, d_ff);
Experts.push_back( FFN );
}
}
matrixd MoE::Scores(const matrixd& X)
{
matrixd WRT = transpose( WR );
matrixd S = matmul(X, WRT);
|
class DSblock {
protected:
    MultiHeadAttention mha;
    AddnNorm norm1;
    MoE mixOfExpert;
    AddnNorm norm2;
    int nExperts;

    // cache from forward()
    matrixd H;
    matrixd X1;
    matrixd Y;

public:
    DSblock(int dModel, int nHeads, int d_ff, int nExperts);
    matrixd forward(const matrixd &X);
    matrixd backward(const matrixd &X, const matrixd &dL_dY, double eta);
    void saveWeights(FILE *fp);
    void readWeights(FILE *fp);
};

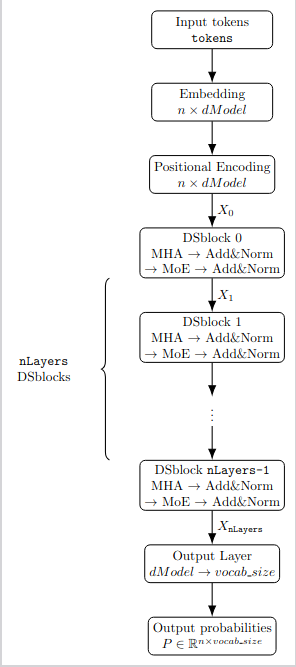
class MiniDS {
protected:
    Embedding embed;
    PositionalEncoding pe;
    vector<DSblock> layers;
    OutputLayer output;

    int seq_len, vocab_size;
    int nExperts;

public:
    MiniDS(int vocab_size, int seq_len, int dModel,
		    int nHeads, int d_ff, int nLayers, int nExperts);
    matrixd forward(const vector<int> &tokens);
    double trainStep(const vector<int> &tokens, double eta);
    int saveWeights(char fname[]);
    int readWeights(char fname[]);
};
|
// Constructor of Dsblock
DSblock::DSblock(int dModel, int nHeads, int d_ff, int nExperts)   // Decoder
    : mha(dModel, nHeads), norm1(dModel),  norm2(dModel),
       nExperts(nExperts), mixOfExpert(nExperts, dModel, d_ff)
{
    // Each MoE block contains nExperts FeedForward networks.
    // The router inside mixOfExpert selects one expert for
    // each token (top-1 routing).
}

// Constructor of MiniDS
MiniDS::MiniDS(int vocab_size, int seq_len, int dModel, int nHeads, int d_ff,
        int nLayers, int nExperts) : embed(vocab_size, dModel), pe(seq_len, dModel),
        output(dModel, vocab_size), seq_len(seq_len), vocab_size(vocab_size),
        nExperts(nExperts)
{
    // Create the stack of DeepSeek-style Transformer blocks.
    //
    // Each DSblock contains:
    //
    //   Masked Multi-Head Self-Attention
    //          ↓
    //      Add & Norm
    //          ↓
    //         MoE
    //          ↓
    //      Add & Norm
    //
    // Each MoE contains nExperts FeedForward experts.

    layers.reserve(nLayers);
    for (int i = 0; i < nLayers; i++) {
       DSblock dsBlock(dModel, nHeads, d_ff, nExperts);
       layers.push_back(dsBlock);
    }
}
|